Analytics Agent: Text-to-SQL with Guardrails
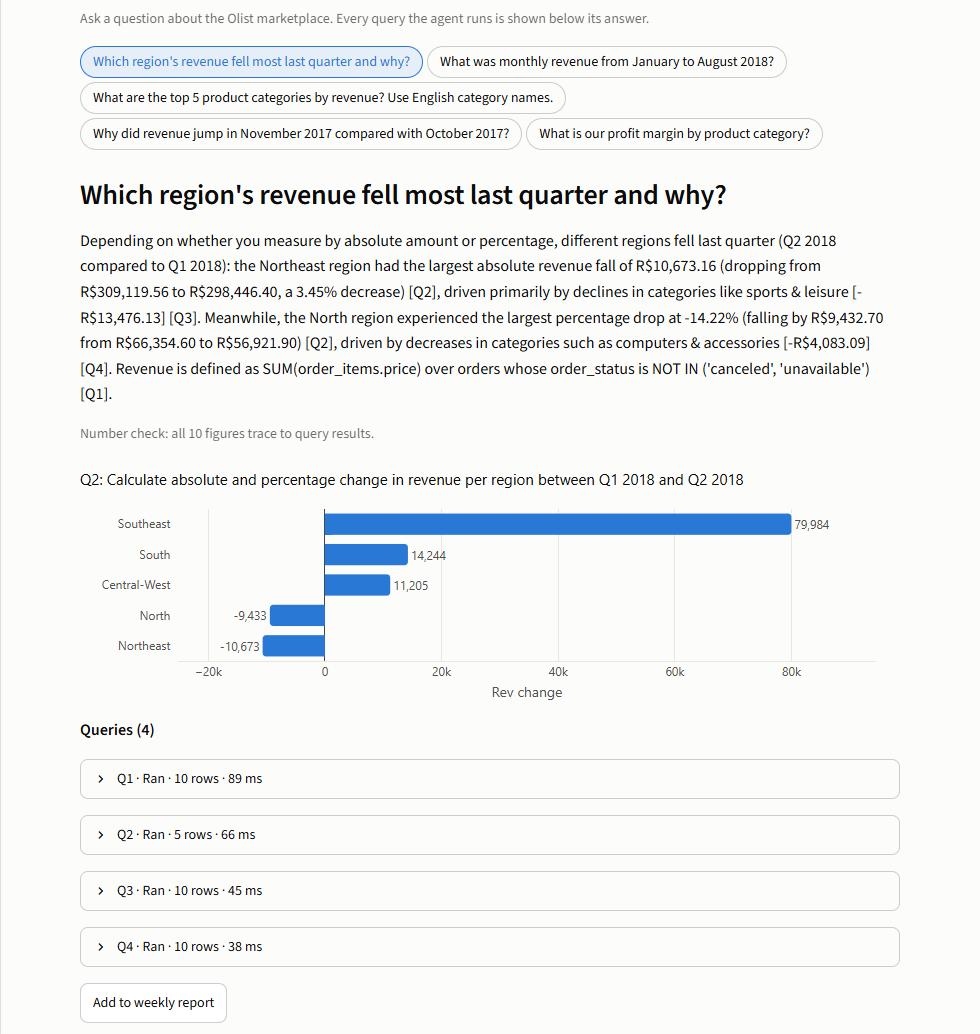
A natural-language data analyst over a SQL database. It inspects the schema, writes SQL, runs it read-only, retries on errors, and answers with a chart, citing the exact queries behind every claim.
View the code on GitHubFull results
- execution accuracy with business definitions, up from 67%
- 93%
- answer accuracy across all 30 questions
- 90%
- automated tests, including 38 refused attacks
- 185
Problem
Business users have questions, and the answers sit in a database they cannot query. Connecting an LLM to that database raises three risks: generated SQL must never change data, a query can run perfectly and still be wrong, and an answer nobody can check is worth little.
Approach
- A bounded tool-calling loop over the public Olist e-commerce dataset, capped at 6 model calls per question.
- Three independent guardrails: an allow-list SQL validator, a locked read-only connection, and execution limits.
- Every answer cites its queries, and a deterministic check traces each figure back to a query result.
- A weekly PDF report uses fixed KPI queries and falls back to a template if the written paragraph fails the number check.
Results
- The gain came from business knowledge, not SQL skill. Plain-prompt SQL always ran, but running is not the same as being right.
- On execution, 7 questions were correct only with the enhanced prompt and 0 only with the plain prompt (exact McNemar p = 0.016).
- The flagship question counts as a miss under the enhanced prompt: the rubric was fixed before the run, and I did not loosen it afterwards.
- Gold answers were derived twice, in SQL and separately in pandas, and all 27 agree.
Limitations
- One model, one dataset and one run, so intervals are wide.
- The number check proves a figure exists in a result, not that the sentence around it is right.
- "Why" answers show association, not cause.
- Only Gemini has been run live; the Anthropic and OpenAI paths use fake clients in tests.
Built with
- Python
- DuckDB
- sqlglot
- pandas
- Plotly
- Streamlit
- ReportLab
- Gemini
- Anthropic
- OpenAI